A locked-out employee at 8:05 a.m. needs a different response than a request for a new monitor, yet many businesses send both into the same inbox. That is where work stalls. Learning how to route IT tickets means getting each request to the right person, with the right priority and enough context to act, without making employees chase updates.
For a small or mid-sized business, ticket routing does not need to become a complicated IT project. It needs to reflect how your people actually work: which problems stop revenue, which requests carry security risk, who owns each system, and when a technician needs to step in.
Start with a clear intake point
If requests arrive through hallway conversations, personal texts, email chains, and chat messages, no routing rule can fully fix the problem. The first step is giving staff one obvious way to ask for help. It can be an email address, a service desk portal, a Teams channel, or an assistant that accepts requests in plain language.
The goal is not to force employees through a long form. Someone who cannot print shipping labels or access a client file needs a quick path to help. At minimum, collect the employee’s name, location or department, the system affected, a brief description, and whether work has stopped. A screenshot or exact error message is useful when available, but it should not be a condition for opening the request.
Good intake also prevents requests from disappearing because one helpful employee happened to be away. The work belongs in a shared queue, where ownership and status are visible.
Define priority by impact, not by who asks loudest
Urgency and importance are related, but they are not the same thing. A printer issue may be urgent if an entire dispatch team cannot produce bills of lading. The same issue may be routine if one office printer is unavailable while another is nearby.
Set a short, plain-language priority model that employees and managers can understand. Four levels are usually enough:
- Critical: A widespread outage, suspected security incident, ransomware alert, or a business-critical system that is unavailable for many people.
- High: A single employee or small team cannot perform a core job function, such as processing payroll, accessing case files, or taking customer payments.
- Normal: A problem has a workaround, or a request is needed soon but does not stop work, such as software access for a new hire.
- Low: Convenience requests, minor changes, equipment moves, or questions that can wait for scheduled support.
Write down real examples from your business. A construction office may treat tablet access to plans as high priority. A law firm may prioritize document-management access. A retailer may put point-of-sale outages at the top of the list. Generic priority definitions are a starting point, not a substitute for your operating reality.
Route by request type and ownership
The fastest technician is not always the right technician. Password resets, account access, Microsoft 365 issues, printers, line-of-business software, phones, and network problems often require different permissions or knowledge. Routing rules should recognize that from the first request.
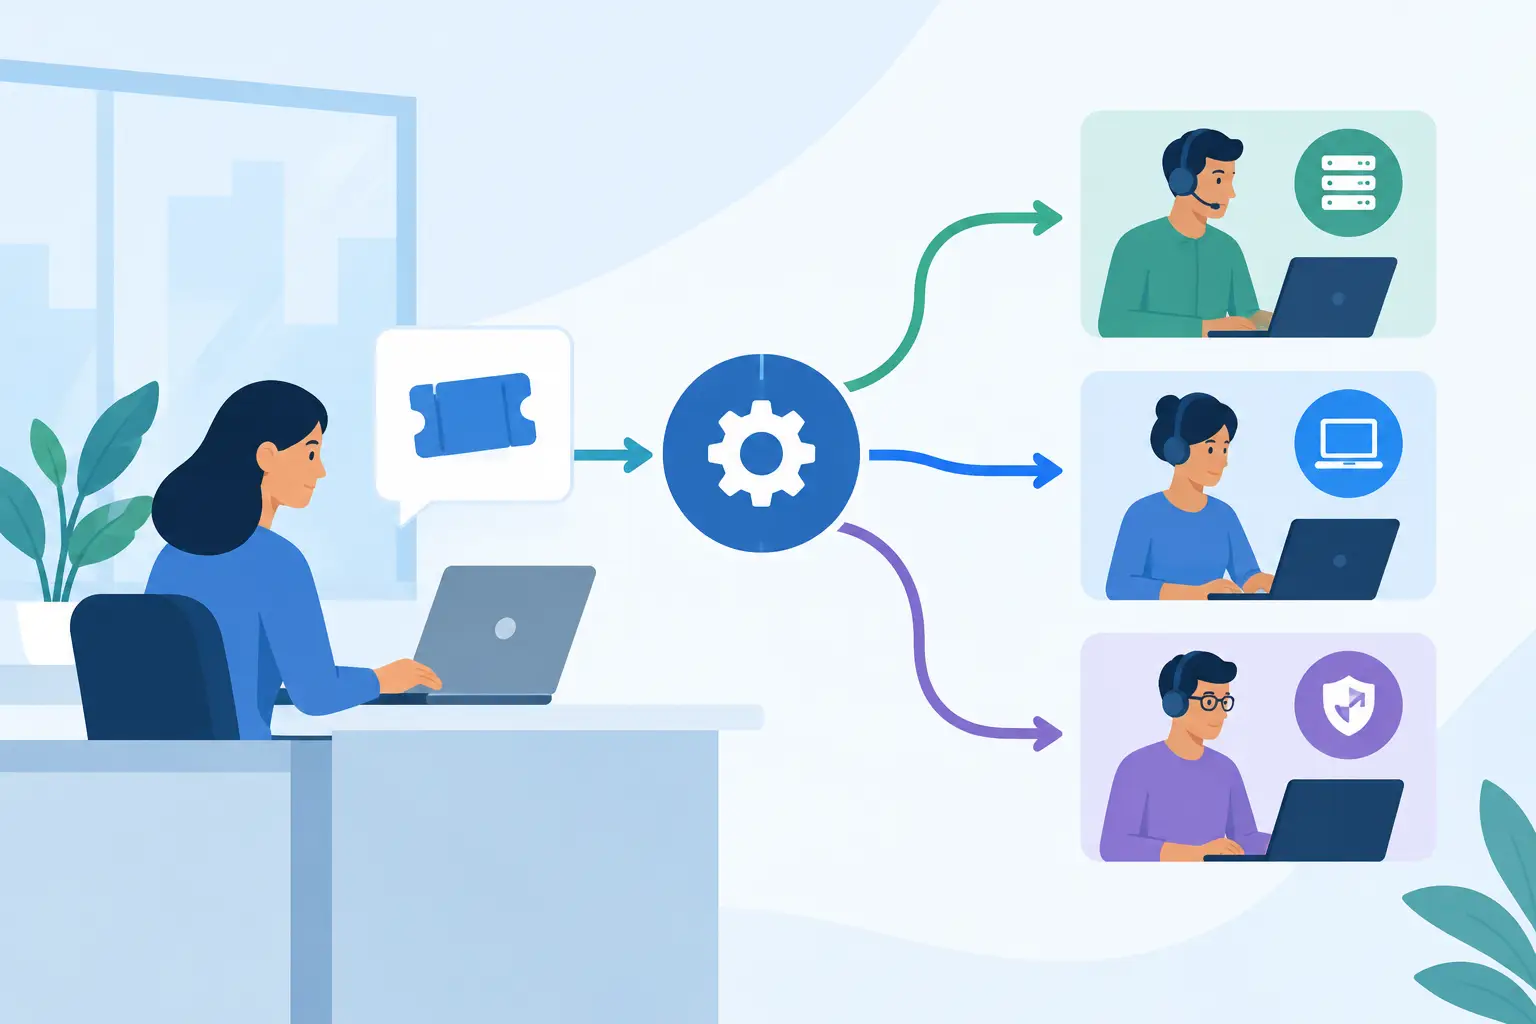
Begin with a small set of categories based on the work you support every week. For example, access and passwords can go to frontline support; device and printer issues can go to desktop support; internet, Wi-Fi, and firewall alerts can go to network support; and accounting or industry-specific application issues can go to the assigned application owner.
Some tickets should never wait in the general queue. Reports of phishing emails, unusual account sign-ins, lost devices, payment redirection requests, or possible data exposure should automatically go to a security-aware technician or manager. Speed matters, but so does making sure the person handling the ticket knows what to preserve, who to notify, and what not to change.
There is a trade-off here. Too many categories make intake confusing and lead to misclassification. Too few categories create a catch-all queue where specialists spend time sorting instead of fixing. Most smaller organizations are better served by a handful of useful categories and a review process for the exceptions.
Use automation for repeatable first steps
Not every ticket needs a human to decide where it belongs. Repetitive requests are a good place to use rules and guided automation. If an employee says, “I’m locked out of my account,” the system can verify identity, offer the approved reset process, and create or update a ticket only if the issue remains unresolved.
The same approach can help with common requests such as software installation, shared mailbox access, onboarding checklists, printer troubleshooting, and VPN connection problems. Automation should gather details, apply known fixes where it is safe, and route the remaining work with a clean record of what has already been tried.
That last part matters. Nothing frustrates an employee more than explaining the same issue three times because the ticket moved between people without notes. A well-routed ticket includes the original request, relevant device or account information, actions already attempted, and the reason it was escalated.
Automation is not the right answer for every situation. A vague complaint such as “my computer is acting strange” may need a person to ask follow-up questions. A suspected security issue should follow your incident process, not a generic troubleshooting script. The practical test is simple: automate predictable, low-risk work and keep a human review point for anything sensitive, unusual, or business-critical.
Set escalation rules before the queue gets busy
Routing is only useful if stuck tickets move forward. Define what triggers escalation: a ticket sitting unassigned, a response deadline that is about to be missed, repeated failed troubleshooting, an executive or customer-facing impact, or a change in severity.
For example, a normal request might be assigned to frontline support with a one-business-day response target. If it cannot be resolved after a set number of attempts, it moves to the appropriate specialist. A high-priority request may alert a technician immediately and notify an operations contact if it threatens a deadline or service commitment.
Avoid routing every difficult ticket directly to the most senior person. That creates a bottleneck and leaves frontline staff unable to solve more over time. Instead, give the first responder a documented set of checks, clear authority to resolve routine issues, and a defined handoff path for work that needs deeper access or expertise.
After-hours coverage also needs a decision. Not every business needs 24/7 response, but every business should know what happens when a critical issue appears outside normal hours. State which events trigger an on-call response, who makes that call, and how employees report the issue. Guessing at 10 p.m. is not a process.
Measure the handoffs that waste time
A ticketing system can produce plenty of reports. Focus on the few measures that reveal whether routing is helping people get back to work. Track time to first response, time to resolution, the percentage of tickets resolved on first contact, the number of reassignments, reopened tickets, and tickets that miss their response target.
Reassignments deserve particular attention. A few are normal. A repeated pattern usually means the category names are unclear, the intake questions are missing something, or responsibility for an application has not been defined. Review a sample of misrouted tickets each month. The answer may be as simple as adding “location” to the intake prompt or clarifying who supports a particular vendor platform.
Also look at the requests that never should have become tickets. If your team receives the same password question every Monday or the same onboarding request every new hire, there is likely a process worth improving. Better routing is not only about moving work faster. It shows you where repetitive work can be removed.
How to route IT tickets without adding more work
Start small. Map your 10 most common IT requests, assign an owner for each, define what makes each one urgent, and create a simple escalation path. Test the process with real tickets for a few weeks before adding more rules.
A managed AI assistant can help here by accepting plain-language requests, collecting the missing details, handling approved routine tasks, and sending exceptions to a real technician with the right context. The value is not a flashy chatbot. It is fewer manual handoffs, less time spent sorting email, and a person who can take over when the situation calls for judgment.
Your staff should not have to learn IT triage just to get help. Give them one clear place to ask, make the next step visible, and keep improving the routes that repeatedly slow down their day.